Pavel Tokmakov

Pavel Tokmakov

Senior Research Scientist, Toyota Research Institute

At TRI, I lead research on world models for embodied AI: learning predictive models of the physical world from large-scale video and leveraging them to advance robot learning. My background is in video understanding, with a focus on objects: how they move, interact, and persist over time, questions that are central to building predictive models of the physical world. Previously I was a postdoc at CMU with Martial Hebert and Deva Ramanan, and completed my PhD at Inria under the supervision of Cordelia Schmid and Karteek Alahari.

Publications

What 30,000 Hours of Ego-centric Video Does Not Teach

Jiahua Dong, Anurag Bagchi, Yash Jangir, Zubair Irshad, Sergey Zakharov, Martial Hebert, Homanga Bharadhwaj, Yu-Xiong Wang, Vitor Guizilini, Pavel Tokmakov

Preprint, 2026

How far does scaling ego-centric human video take world models? We train on 30,000 hours of video spanning 1,000+ scene types and find that scaling brings agent modeling near saturation but leaves object dynamics far behind. Closing this gap depends on how models are trained, not on data alone.

GPWM: Generative Particle World Models for 3D Prediction and Planning

Robert Ren, Matthew Bronars, He Zhu, Sergey Zakharov, Pavel Tokmakov, Katerina Fragkiadaki

Preprint, 2026

A generative world model that learns 3D physical dynamics from particle trajectories across rigid, deformable, cloth, and granular materials. Beyond prediction, GPWM supports contact-rich planning by backpropagating goal rewards through the learned dynamics.

Walk Through Paintings: Ego-centric World Models from Internet Priors

Anurag Bagchi, Zhipeng Bao, Homanga Bharadhwaj, Yu-Xiong Wang, Pavel Tokmakov*, Martial Hebert*

ECCV, 2026

We present the Egocentric World Model (EgoWM), a simple, architecture-agnostic method that transforms any pre-trained video diffusion model into an action-conditioned world model, enabling precisely controllable future prediction from a first-person view.

AnyView: Synthesizing Any Novel View in Dynamic Scenes

Basile Van Hoorick, Dian Chen, Shun Iwase, Pavel Tokmakov, Muhammad Zubair Irshad, Igor Vasiljevic, Swati Gupta, Fangzhou Cheng, Sergey Zakharov, Vitor Guizilini

ECCV, 2026

A diffusion-based framework for dynamic view synthesis with minimal geometric assumptions, capable of producing zero-shot novel videos from arbitrary camera locations and trajectories — even under extreme viewpoint changes where input and output have little overlap.

CVESC

Capturing Visual Environment Structure Correlates with Control Performance

Jiahua Dong, Yunze Man, Pavel Tokmakov*, Yu-Xiong Wang*

ICLR, 2026

The choice of visual representation is key to scaling generalist robot policies, but direct evaluation via policy rollouts is expensive even in simulation. We propose a proxy task of state prediction from visual inputs that strongly correlates with downstream policy success across environments and architectures, significantly outperforming prior metrics.

Video Generators Are Robust Robot Policies

Junbang Liang, Pavel Tokmakov, Ruoshi Liu, Ege Ozguroglu, Sruthi Sudhakar, Paarth Shah, Rares Ambrus, Carl Vondrick

arXiv, 2025

Pretrained video generators serve as robust visuomotor policies, generalizing under perceptual and behavioral distribution shifts where standard visuomotor policies fail — without relying on additional human demonstration data.

AllTracker: Efficient Dense Point Tracking at High Resolution

Adam W. Harley, Yang You, Xinglong Sun, Yang Zheng, Nikhil Raghuraman, Yunqi Gu, Sheldon Liang, Wen-Hsuan Chu, Achal Dave, Pavel Tokmakov, Suya You, Rares Ambrus, Katerina Fragkiadaki, Leonidas J. Guibas

ICCV, 2025

A dense point tracker that estimates long-range tracks by predicting the flow field between a query frame and every other frame, producing high-resolution dense correspondences across time.

Dreamitate: Real-world Visuomotor Policy Learning via Video Generation

Junbang Liang, Ruoshi Liu, Ege Ozguroglu, Sruthi Sudhakar, Achal Dave, Pavel Tokmakov, Shuran Song, Carl Vondrick

CoRL, 2024

A visuomotor policy learning framework that fine-tunes a video diffusion model on human demonstrations, generating task executions to control robots with improved generalization to novel objects and environments.

Zero-1-to-3

Zero-1-to-3: Zero-shot One Image to 3D Object

Ruoshi Liu, Rundi Wu, Basile Van Hoorick, Pavel Tokmakov, Sergey Zakharov, Carl Vondrick

ICCV, 2023

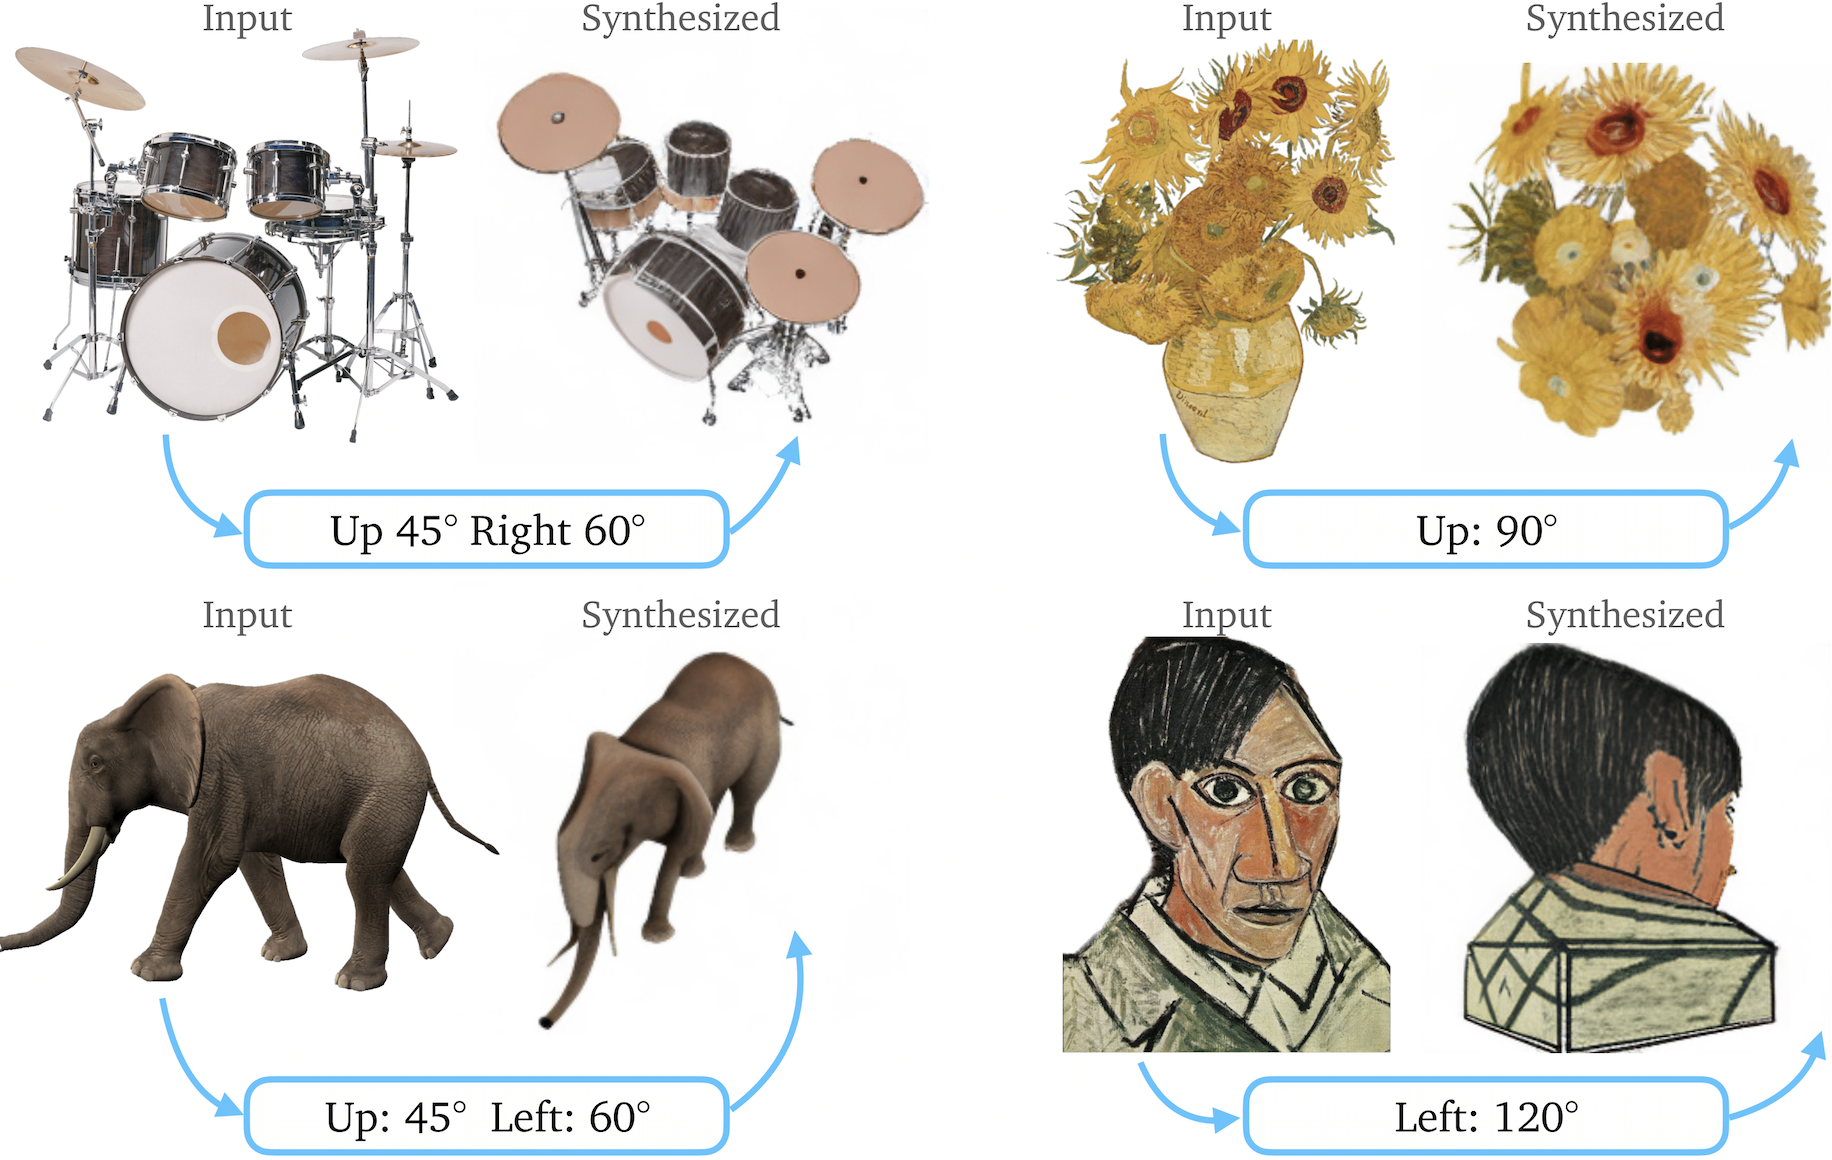
A framework for changing the camera viewpoint of an object given just a single RGB image. To perform novel view synthesis in this under-constrained setting, we capitalize on the geometric priors that large-scale diffusion models learn about natural images.

VOST

Breaking the “Object” in Video Object Segmentation

Pavel Tokmakov, Jie Li, Adrien Gaidon

CVPR, 2023

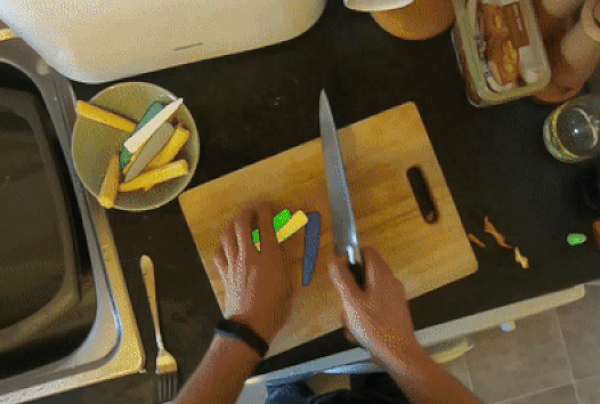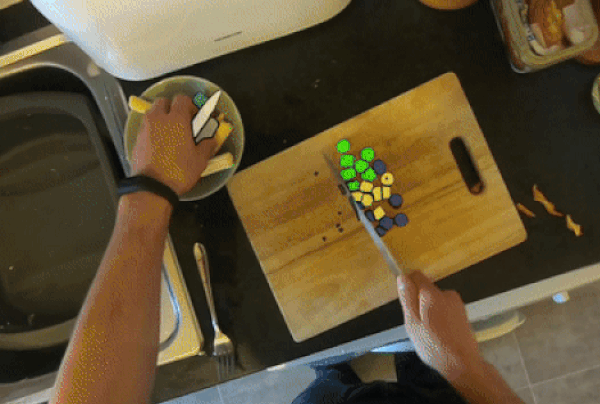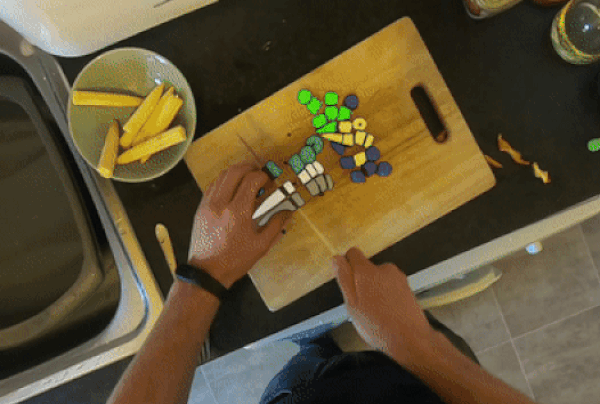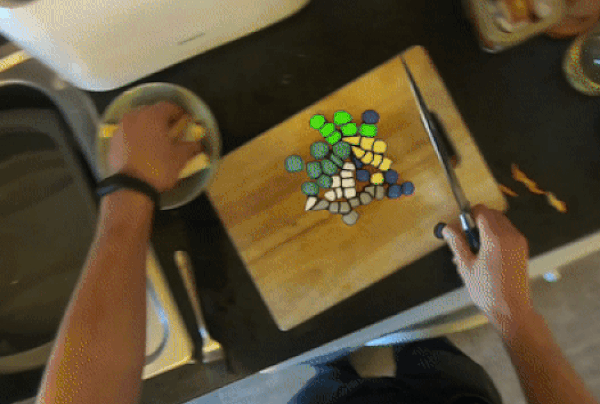
VOST is a semi-supervised video object segmentation benchmark that focuses on complex object transformations. Objects in VOST are broken, torn and molded into new shapes, dramatically changing their overall appearance — a major challenge for mainstream, appearance-centric VOS methods.

RAM

Object Permanence Emerges in a Random Walk along Memory

Pavel Tokmakov, Allan Jabri, Jie Li, Adrien Gaidon

ICML, 2022

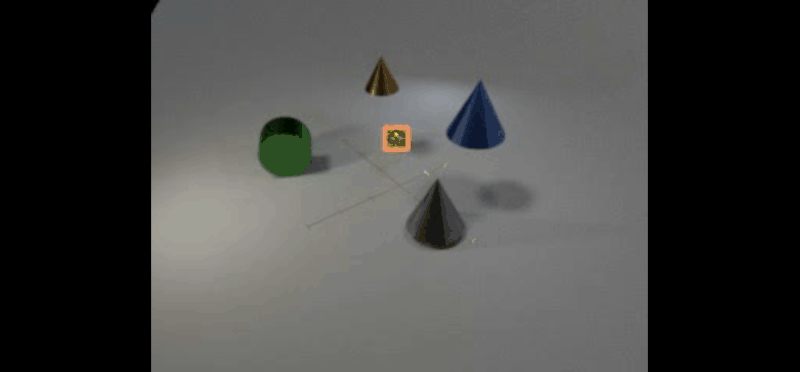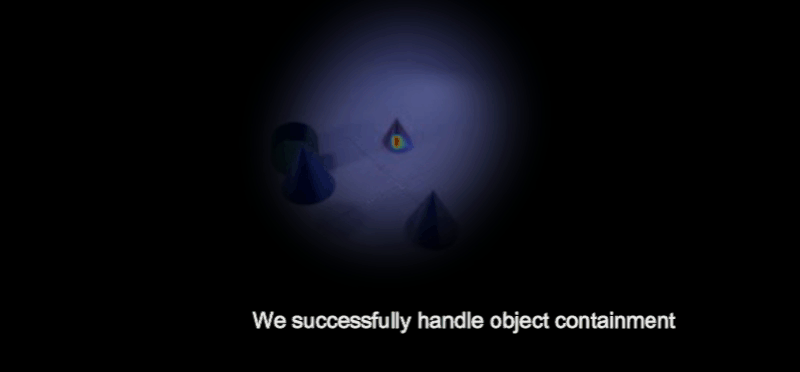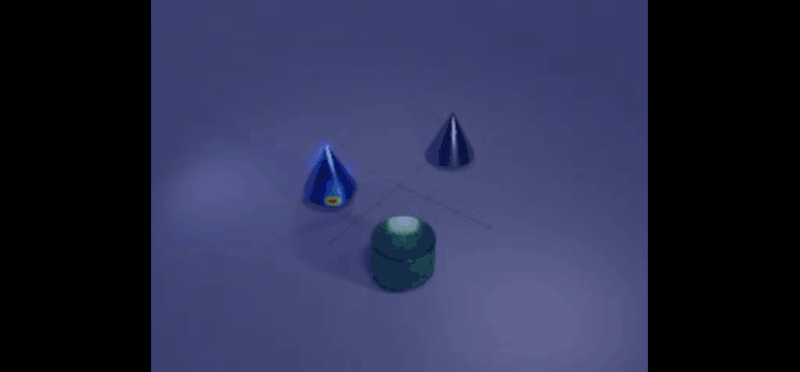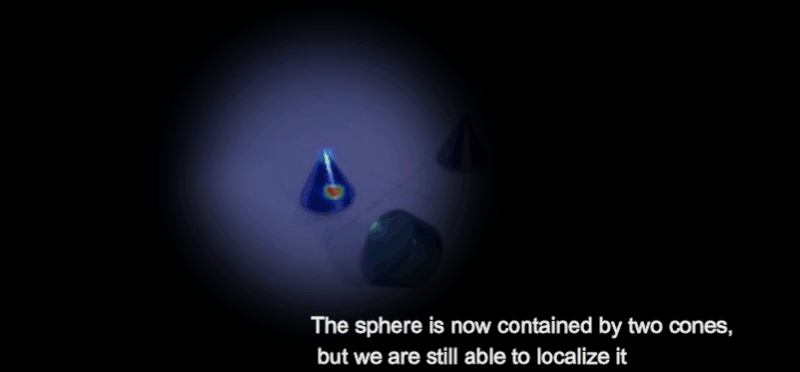
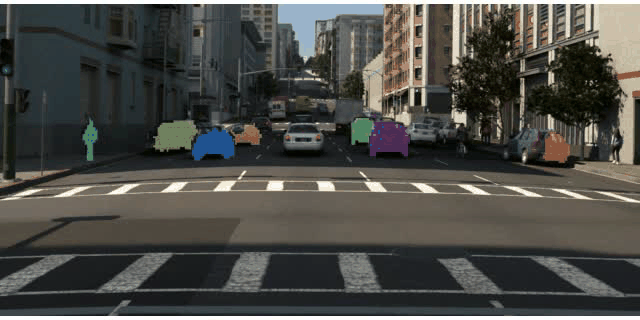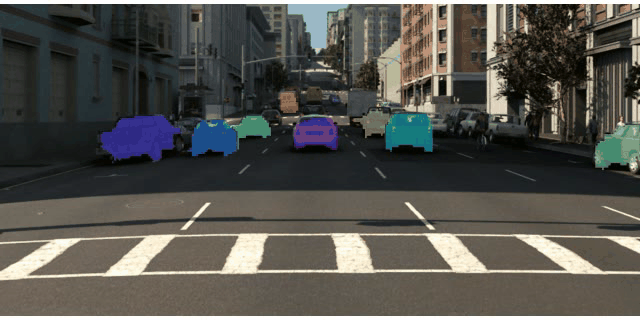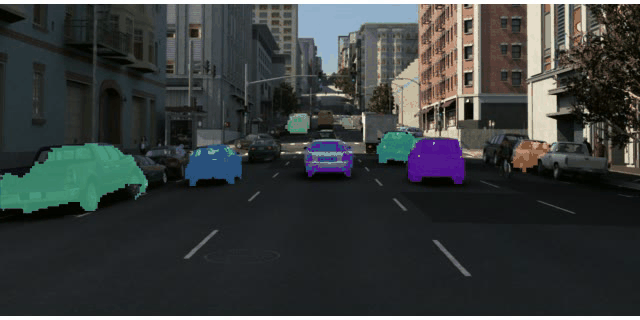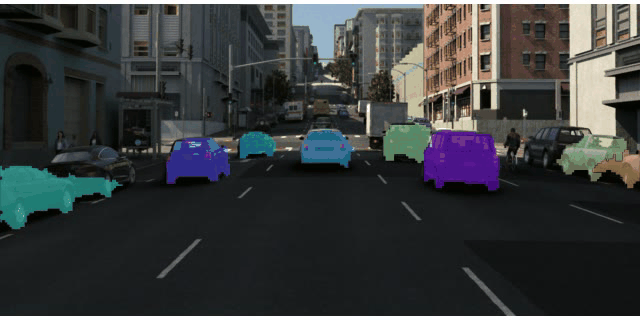
A self-supervised objective for learning representations that localize objects under occlusion — a property known as object permanence. Rather than directly supervising the locations of invisible objects, we propose an objective that requires neither human annotation nor assumptions about object dynamics.

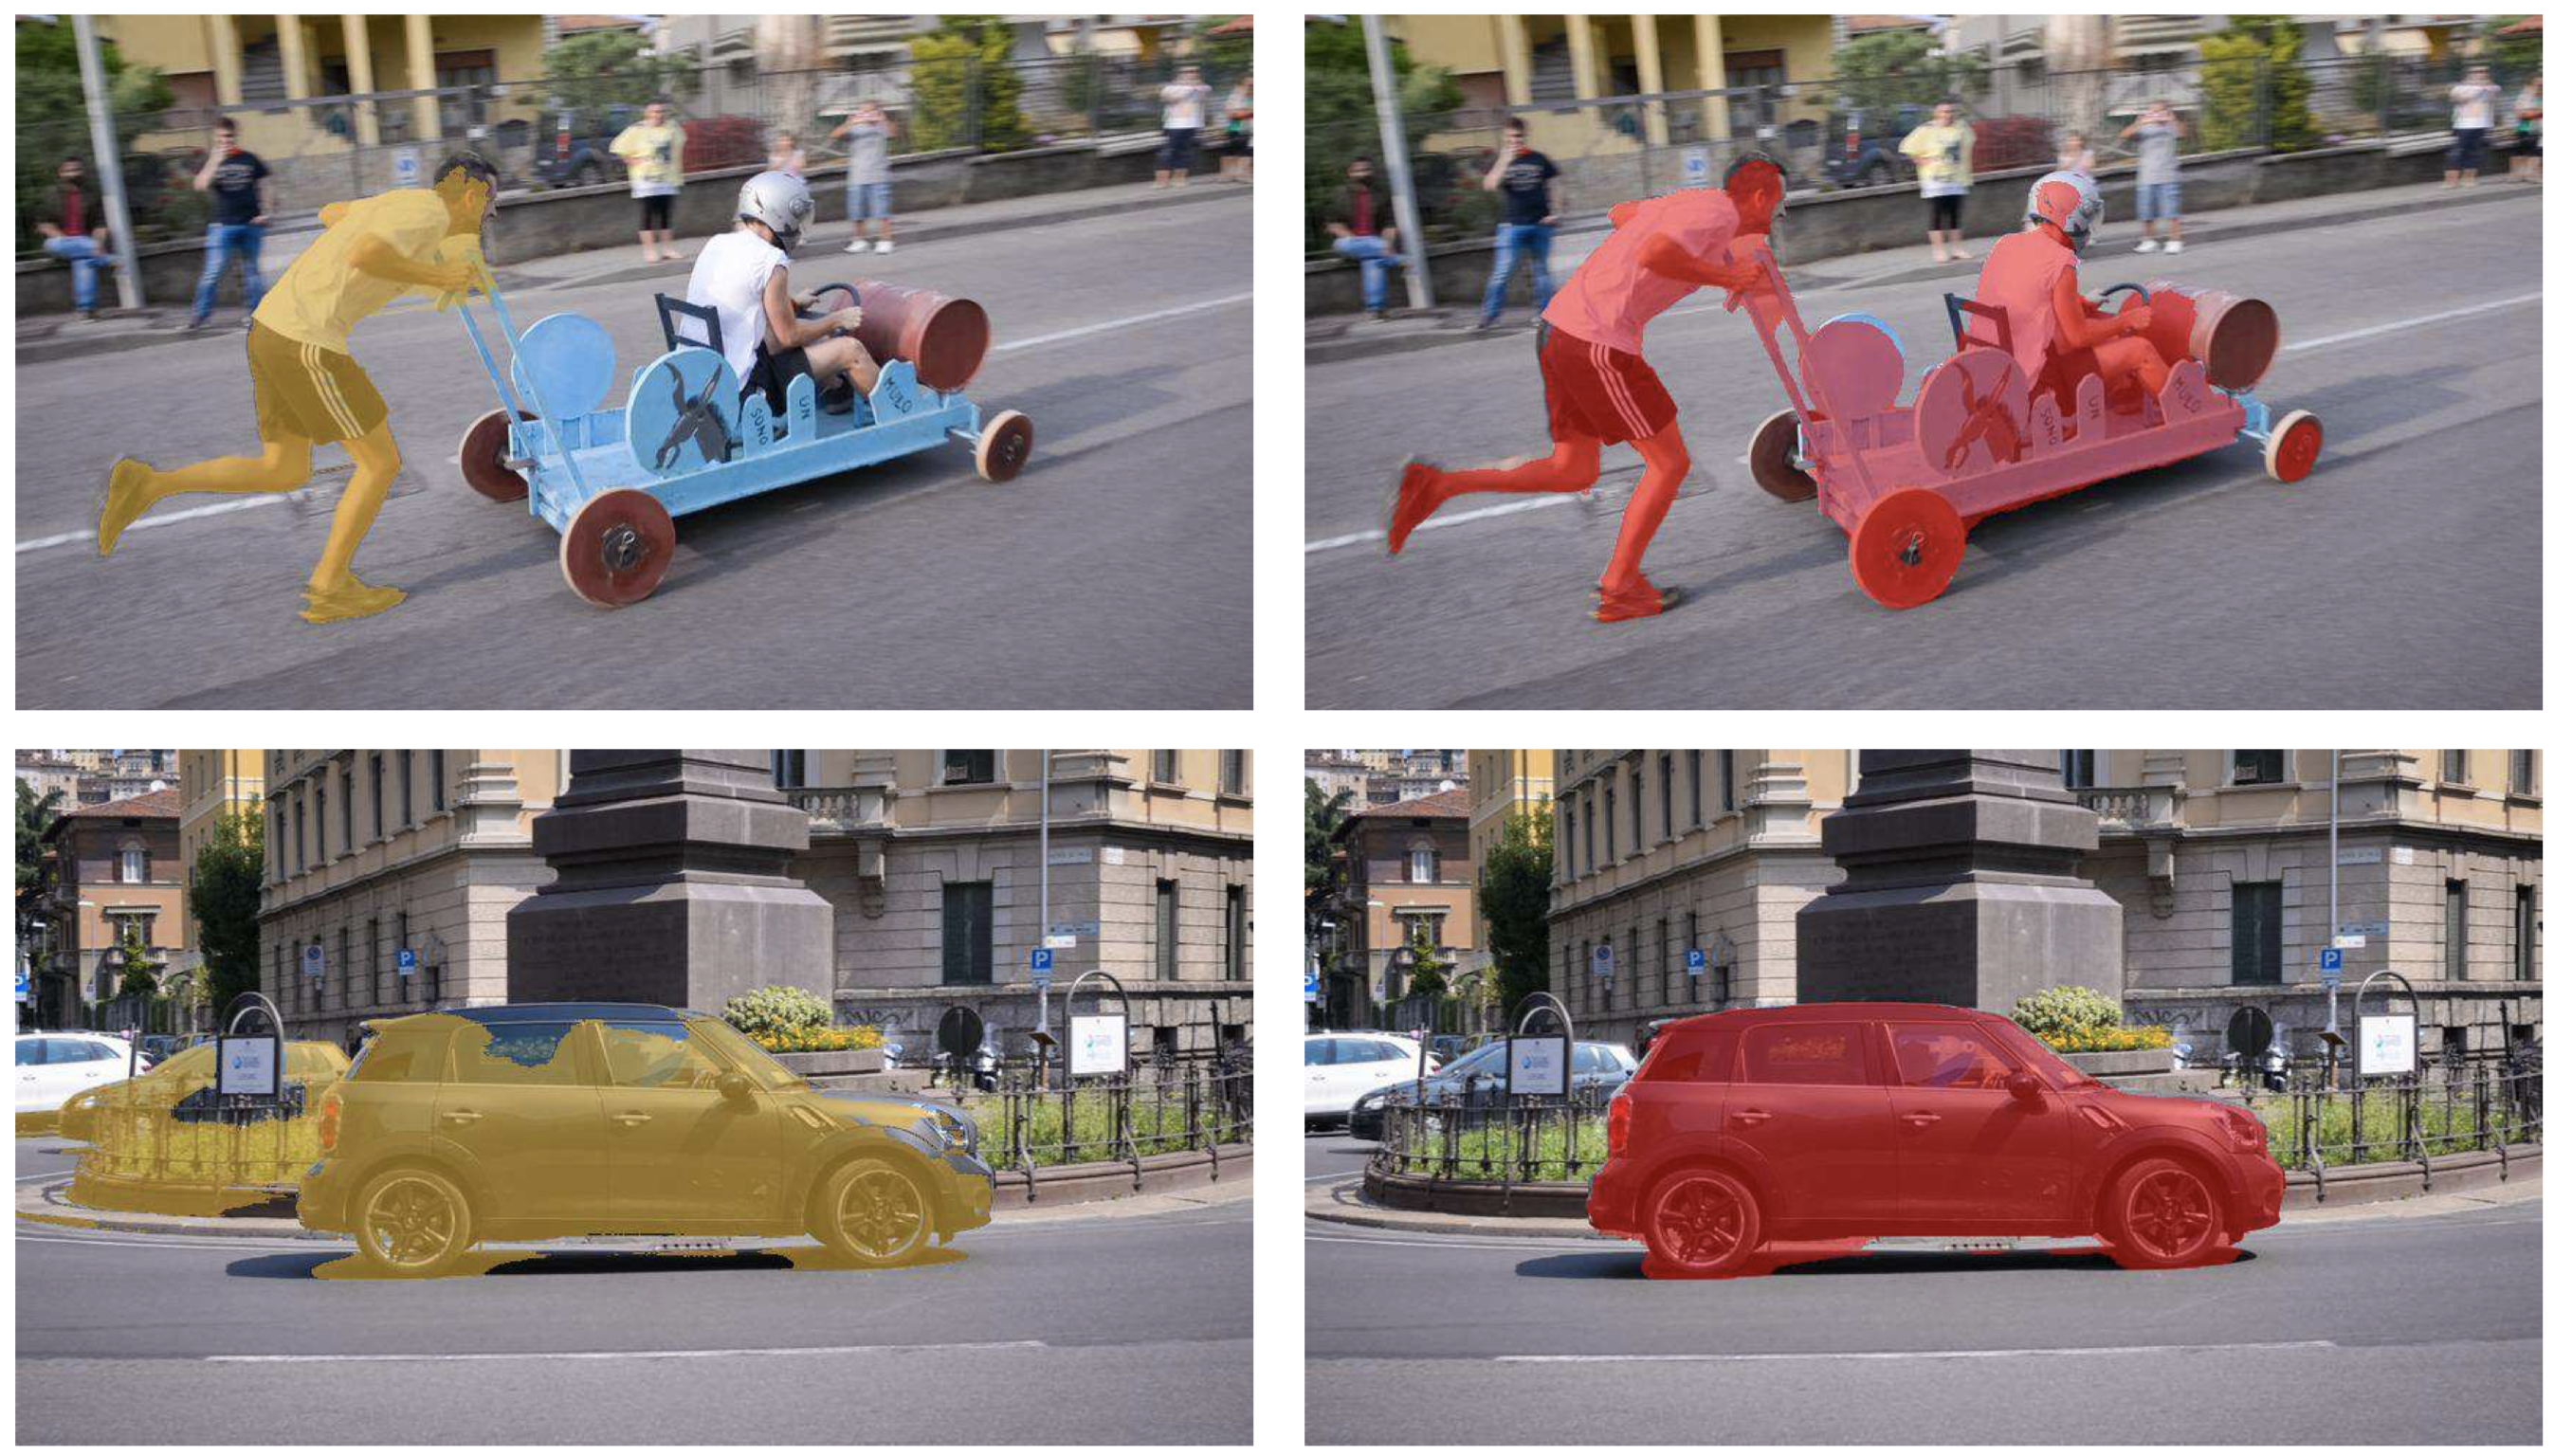
Discovering Objects that Can Move

Discovering Objects that Can Move

Zhipeng Bao*, Pavel Tokmakov*, Allan Jabri, Yu-Xiong Wang, Adrien Gaidon, Martial Hebert

CVPR, 2022

Existing object discovery methods rely on appearance cues — color, texture, location — and fail in cluttered scenes. We instead focus on dynamic objects: entities capable of moving independently in the world, using motion as a bottom-up cue.

Learning to Track with Object Permanence

Pavel Tokmakov, Jie Li, Wolfram Burgard, Adrien Gaidon

ICCV, 2021

PermaTrack extends tracking-by-detection with object permanence — the ability to reason about objects that are temporarily invisible due to occlusion or leaving the field of view — for online multi-object tracking.

TAO

TAO: A Large-Scale Benchmark for Tracking Any Object (Spotlight)

Achal Dave, Tarasha Khurana, Pavel Tokmakov, Cordelia Schmid, Deva Ramanan

ECCV, 2020

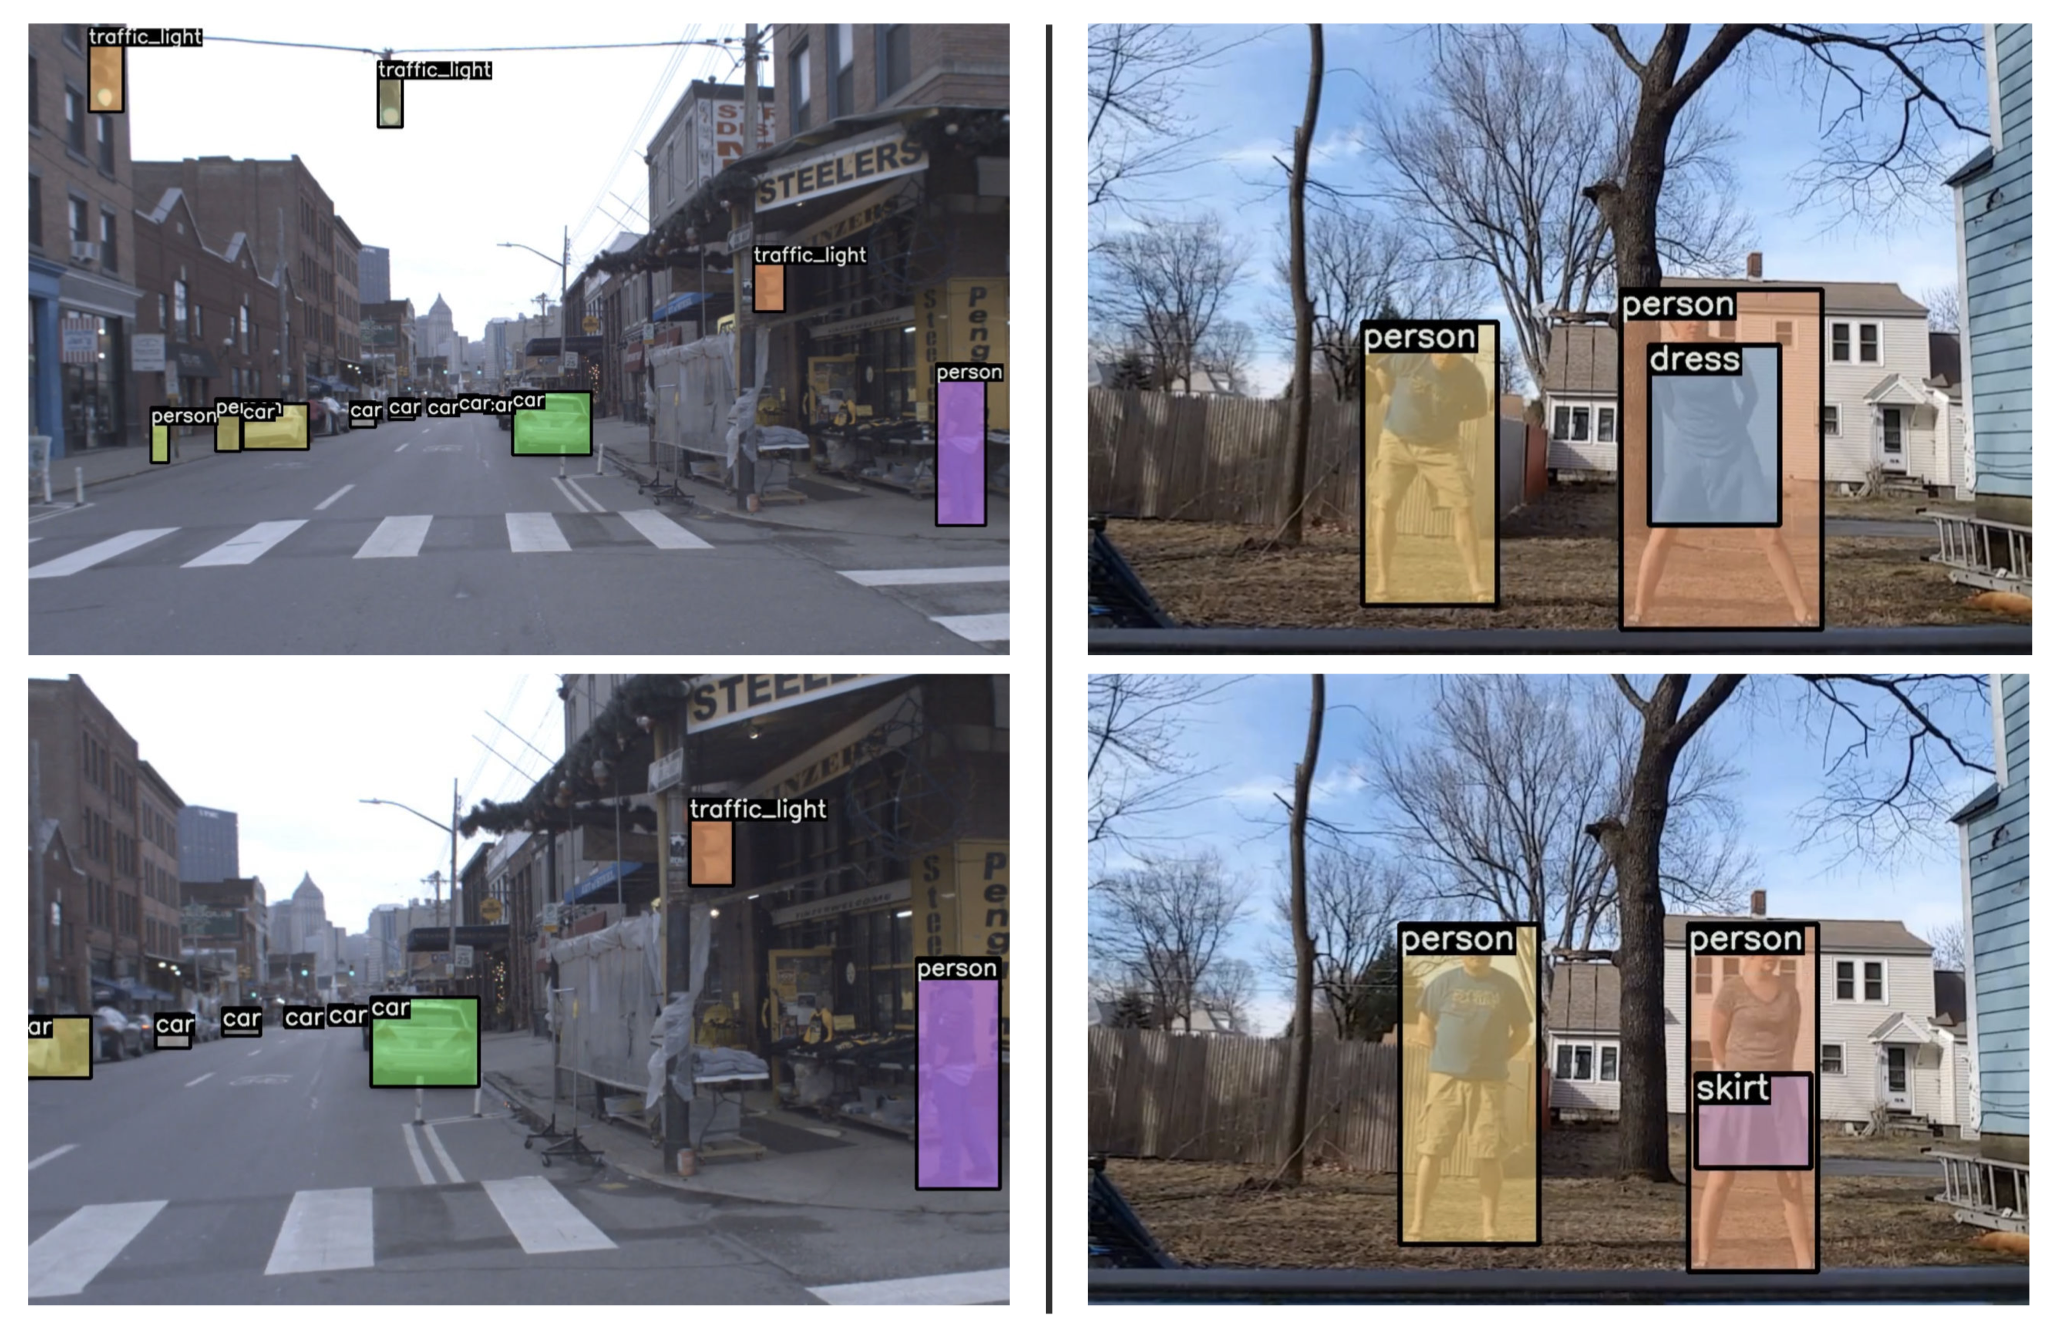
Multi-object tracking benchmarks had long focused on a handful of categories. TAO is a diverse dataset for Tracking Any Object: 2,907 high-resolution videos covering 833 categories, with an extensive evaluation of state-of-the-art trackers in the open-world setting.

Show earlier work
Compositional Few-Shot

Learning Compositional Representations for Few-Shot Recognition

Pavel Tokmakov, Yu-Xiong Wang, Martial Hebert

ICCV, 2019

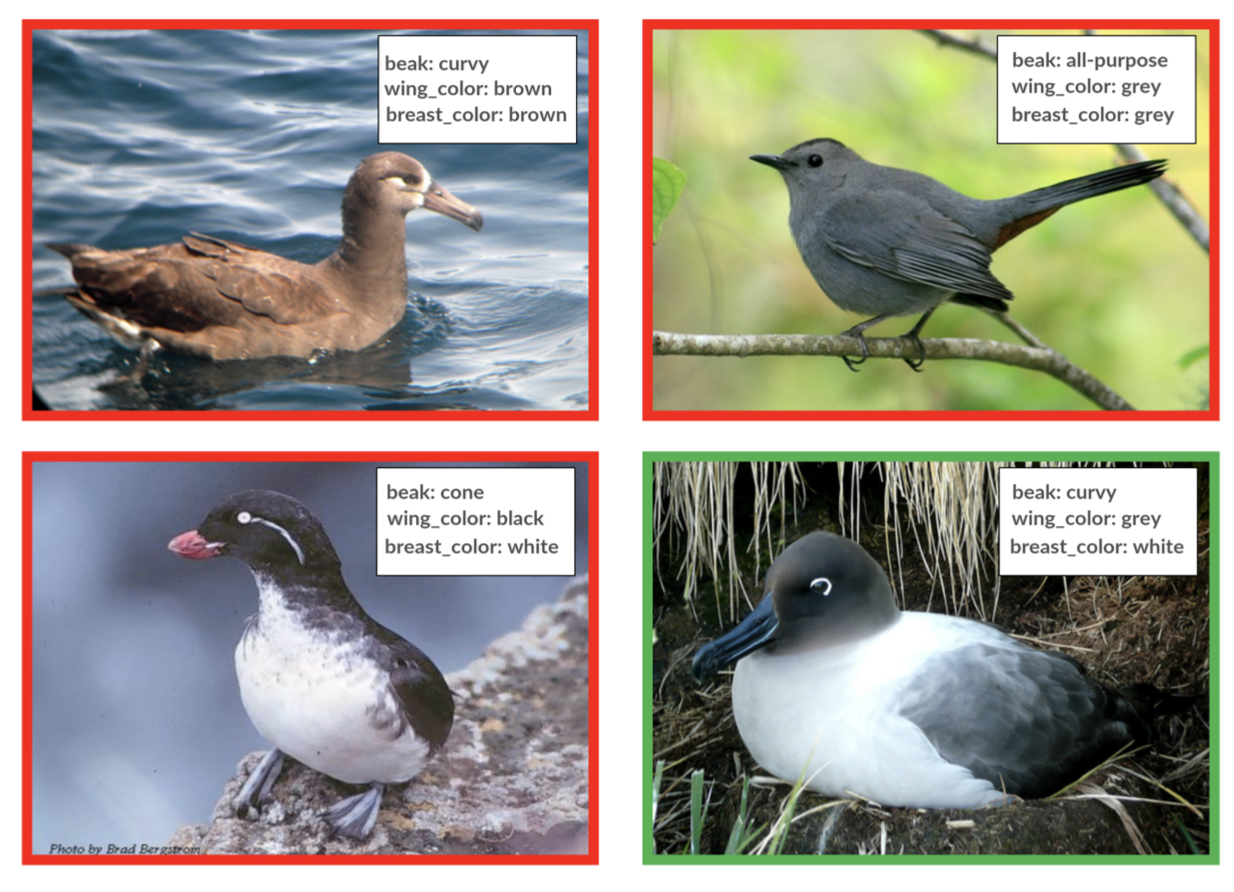
Deep learning representations lack compositionality, which is instrumental for the human ability to learn novel concepts from a few examples. We investigate approaches to enforcing this property during training, yielding significant improvements in the few-shot setting.

Structured Action Detection

A Structured Model For Action Detection

Yubo Zhang, Pavel Tokmakov, Cordelia Schmid, Martial Hebert

CVPR, 2019

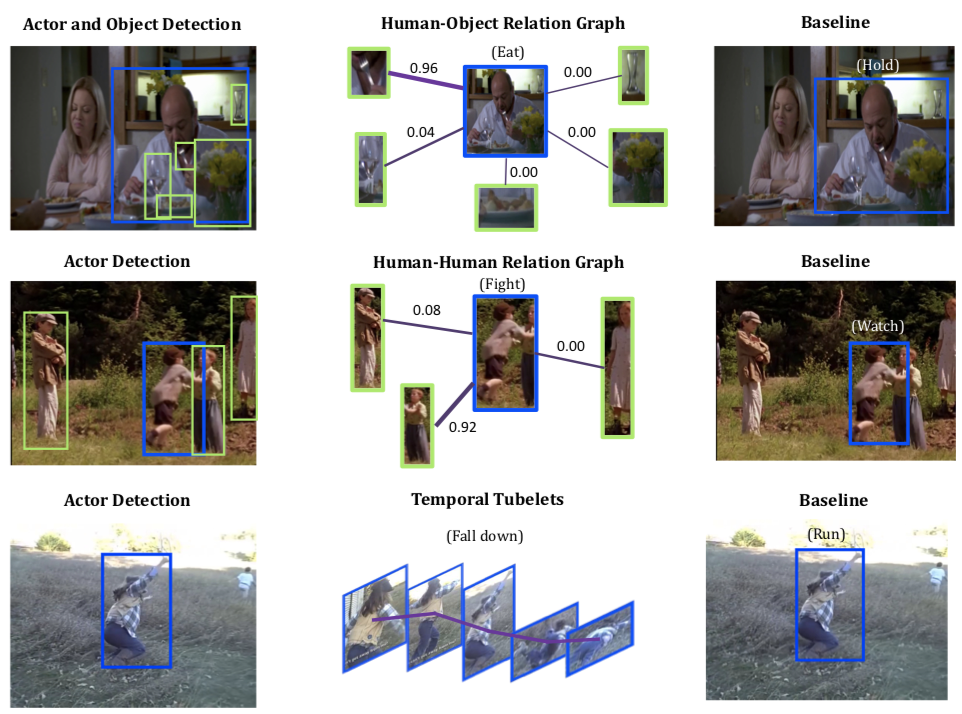
A dominant paradigm in vision is training generic models on large datasets. We instead integrate domain knowledge into the architecture of an action detection model, achieving significant improvements over the state-of-the-art without much parameter tuning.

LVO

Learning Video Object Segmentation with Visual Memory (Oral)

Pavel Tokmakov, Karteek Alahari, Cordelia Schmid

ICCV, 2017

Motion segmentation methods identify moving objects but fail once objects stop moving. We propose a two-stream architecture that combines motion cues with an appearance-based visual memory module, segmenting objects before they start and after they stop moving.

MP-Net

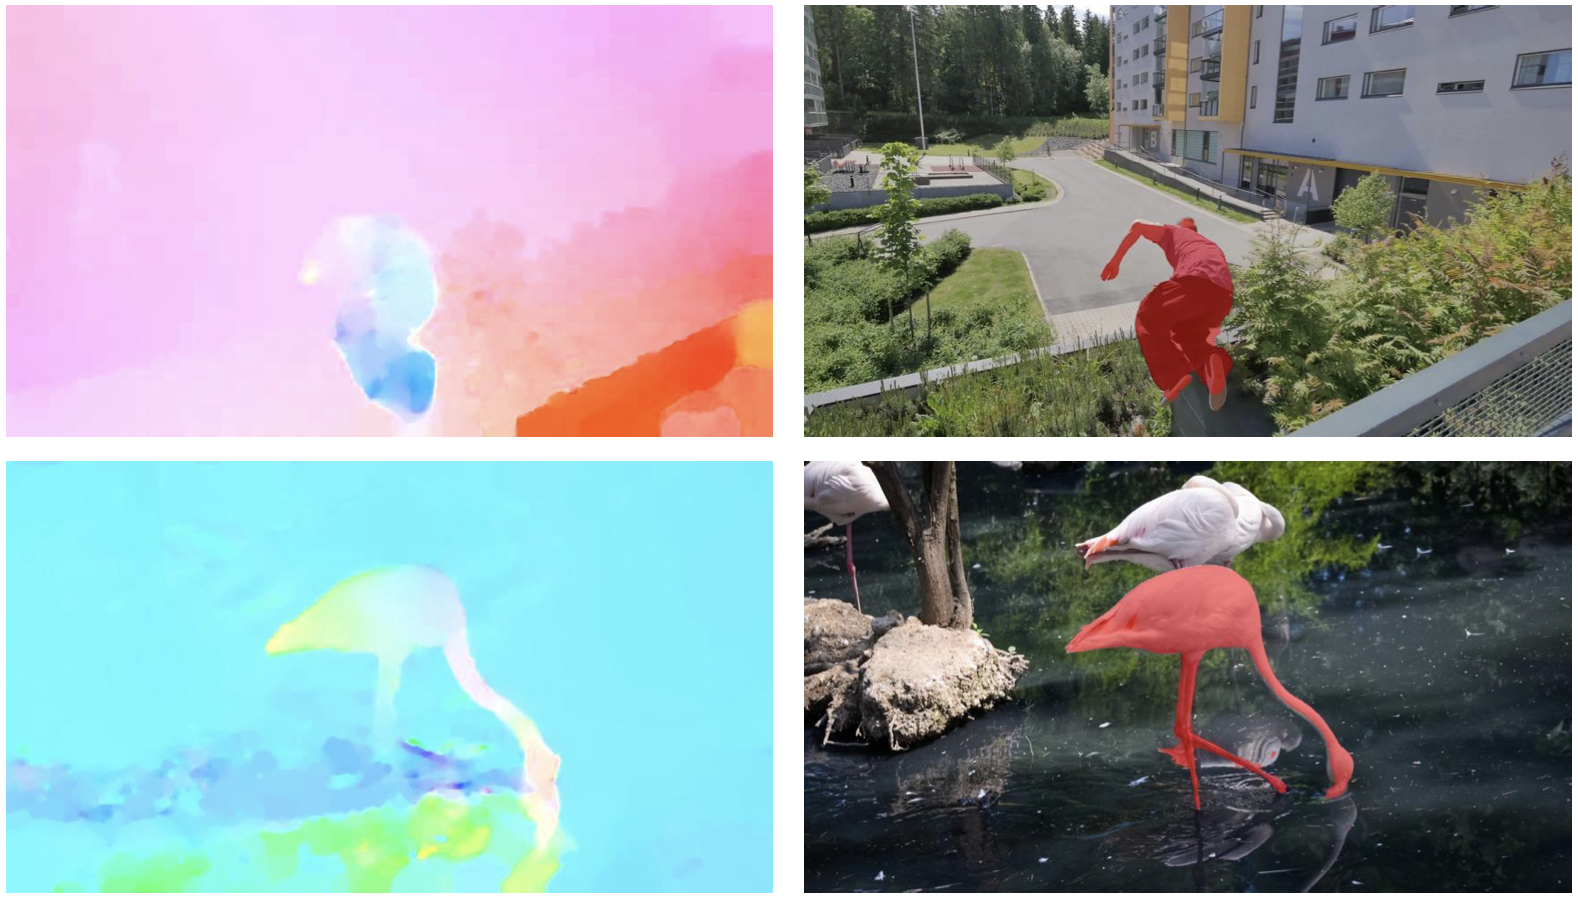
Learning Motion Patterns in Videos

Pavel Tokmakov, Karteek Alahari, Cordelia Schmid

CVPR, 2017

The first learning-based approach for motion segmentation: separating independently moving objects from the background in videos. The model learns to predict per-pixel motion masks directly from optical flow.

Weakly-Supervised Semantic Segmentation

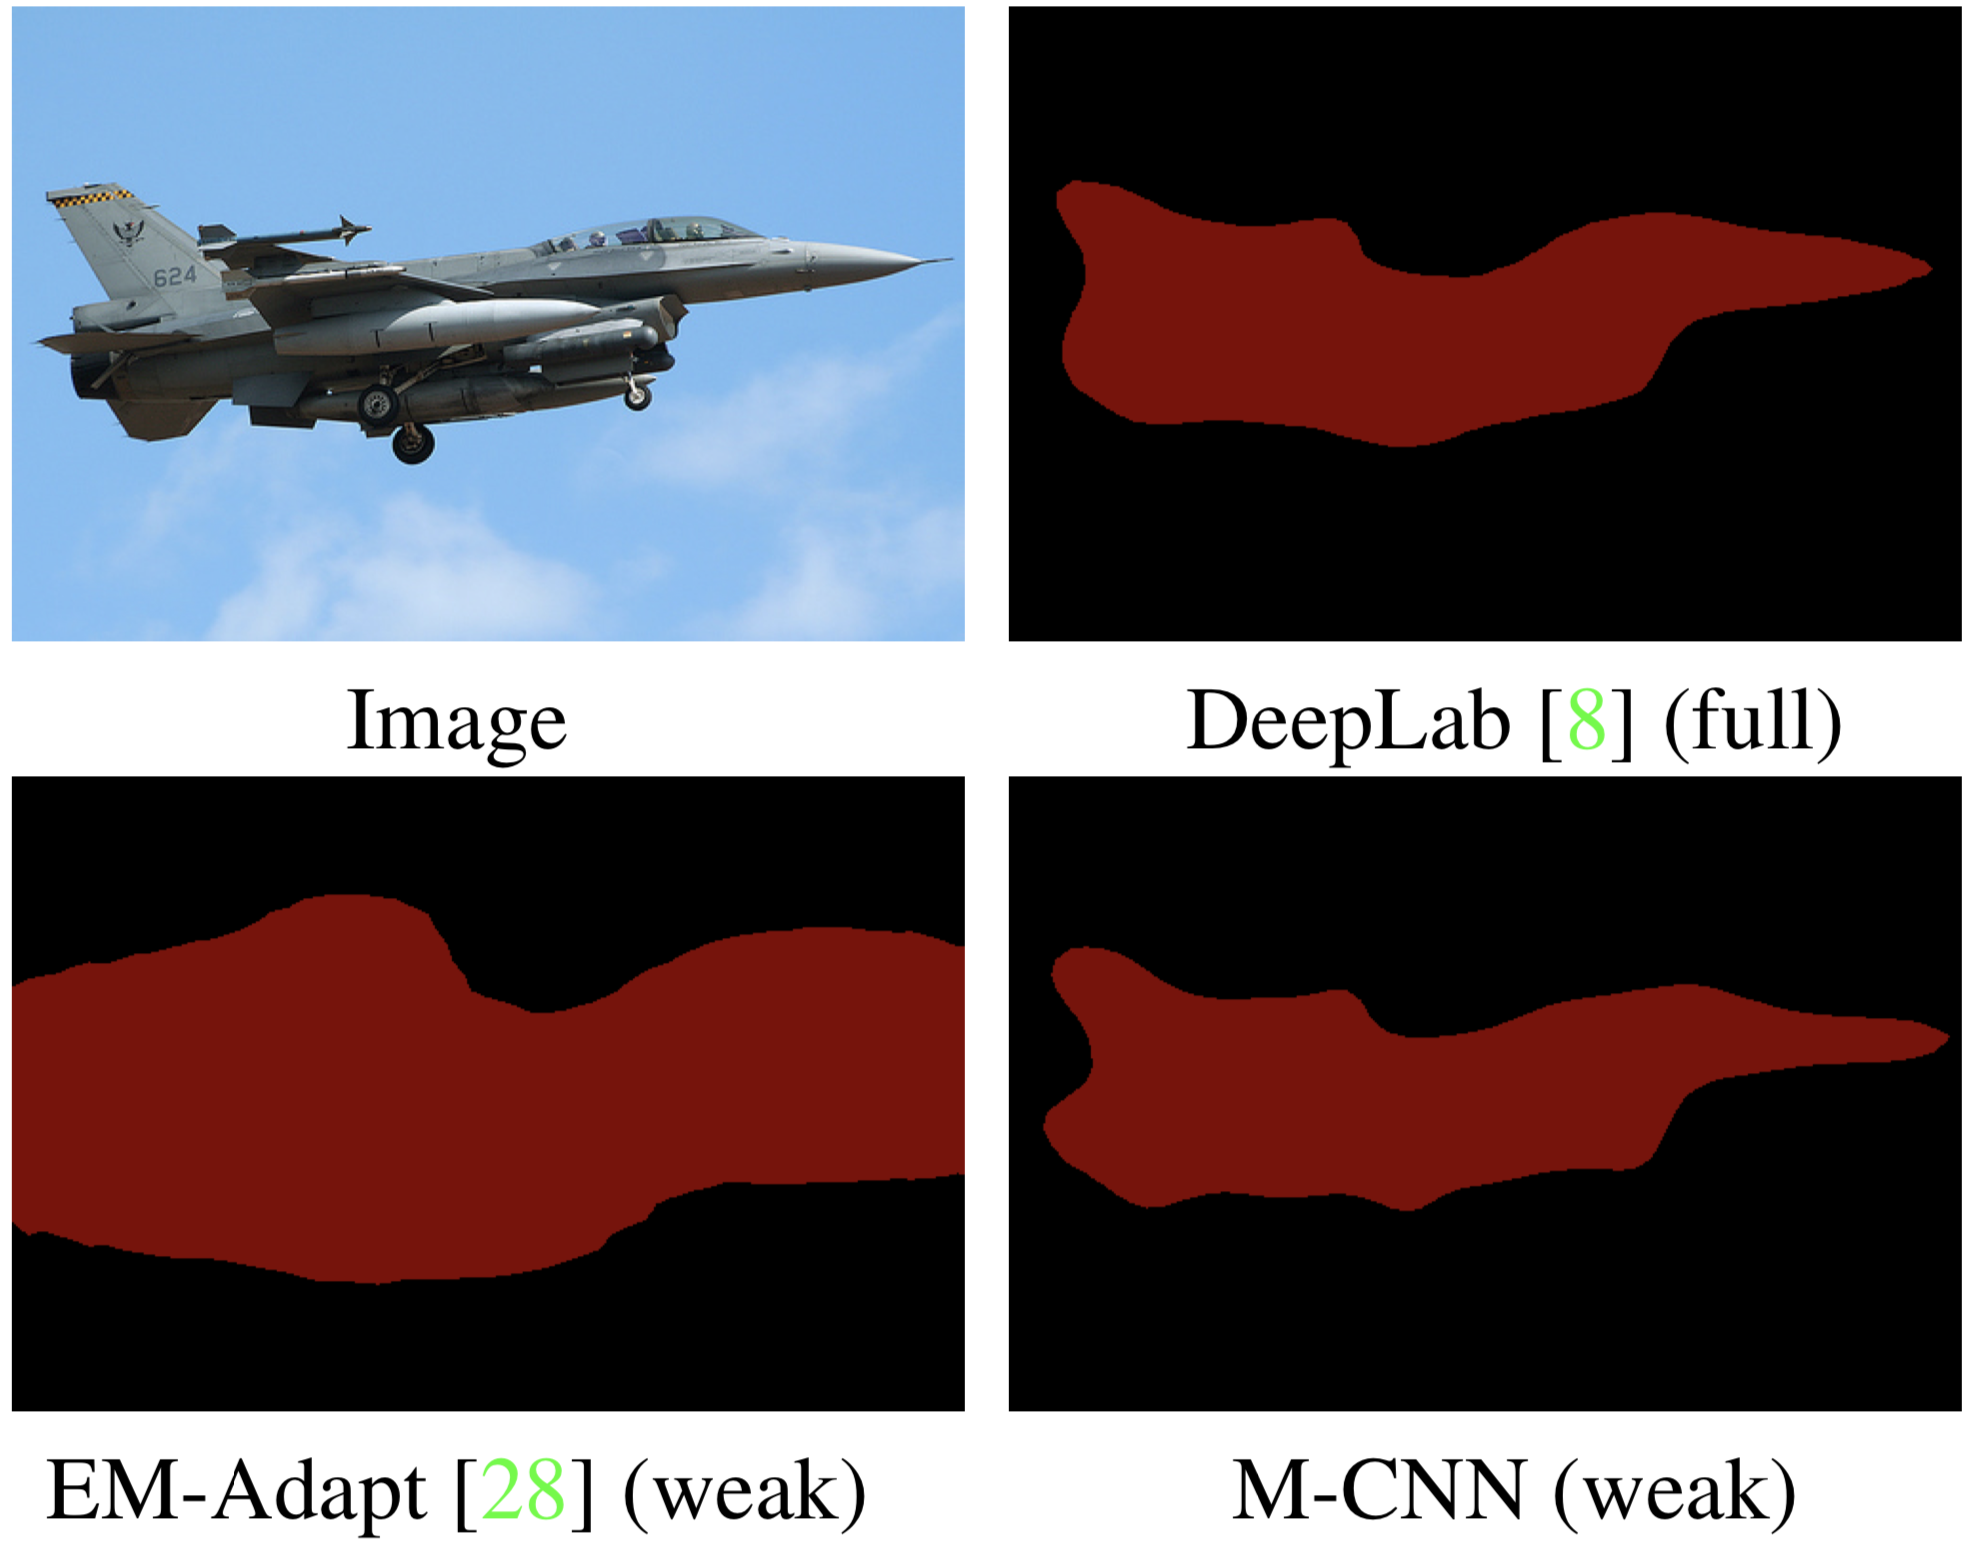
Weakly-Supervised Semantic Segmentation Using Motion Cues

Pavel Tokmakov, Karteek Alahari, Cordelia Schmid

ECCV, 2016

Semantic segmentation models require large amounts of expensive, pixel-level annotations. We reduce this burden by training on weakly-labeled videos and obtaining precise shape information from motion for free, integrating motion cues into a label inference framework.